


The GPU Read 0%. The Miner Never Stopped.
A Linux server can look perfectly healthy while someone else spends its electricity. Elastic Security Labs documented the campaign in late October 2026 and attributed it to REF3364, a financially motivated cluster. At its center is SANSAR, a Rust-based orchestrator that runs cryptocurrency miners on compromised Linux GPU hosts — and works hard to make sure nobody notices.
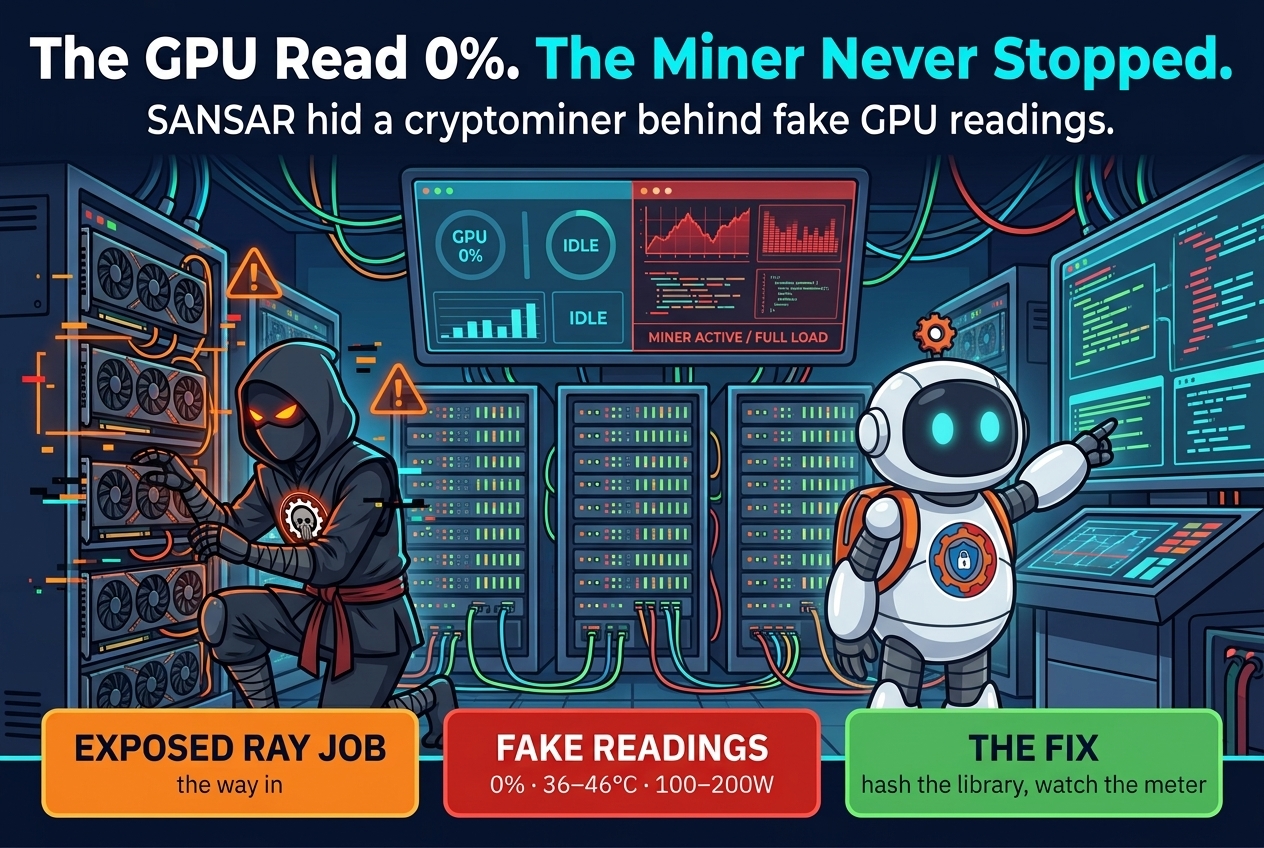
The operation hit three Linux hosts with graphics processors. The miners were real. The dashboard said otherwise.
How they got in
Initial access came through an exposed Ray job agent. Ray is the open-source framework for distributed AI jobs, and its job endpoint lets a user run commands on the cluster. Left facing the internet without controls, anyone can use it. The intruders used it to run jobs calling nvidia-smi, NVIDIA’s system-management tool, to list the GPUs and send the inventory to an external server — checking what hardware was worth stealing.
Next came a Python reverse shell job, connecting back to a listener the attackers controlled. Then an SSH key was added to the account’s authorized_keys file — persistence that survives a password change and barely registers in the logs.
Root — and the toolkit that moved in
Once the attackers had root, the toolkit was staged under /opt/vadi_. A kernel rootkit, acpi_thermal_mgr.ko, was built with DKMS (the kernel-module builder) and paired with an initramfs loader from the early-boot image. Both live in the boot image on disk, so the rootkit loads again at every boot — restarting the server does not clean it.
The rootkit uses ftrace, a kernel tracing feature, to intercept directory listings, file access, and process signals. Matching processes, files, and sockets vanish from the answers — “No such file or directory” or “No such process.” Standard tools report a clean machine because the kernel itself is lying.

The lie in the dashboard
The most unusual piece is a modified NVIDIA Management Library (NVML) wrapper — the library monitoring tools query about GPU workload. The altered wrapper hooks those calls and substitutes fake answers: utilization reported as 0%, temperature as random 36–46°C, power draw as random 100–200W. A mining rig running flat out reads like a card sitting idle.
The usual first sign of cryptojacking — a GPU pinned at 100% — was removed at the source, so anyone watching nvidia-smi or a dashboard fed by NVML saw nothing wrong.

The mining crew
SANSAR is the foreman. It reaches its command server over TOR via the Arti client and supervises the miners: starting or stopping them, pushing config updates, opening shells, and launching an IPv4 TCP SYN flood at a specified address and port on command. First it checks TracerPid — the field showing whether a process is being traced — and exits if it is non-zero.
Its miners are kurt (XMRig 6.25.0, for CPUs) and tilki (SRBMiner-MULTI 3.6.9, for GPUs). Lyrebird, a legitimate TOR pluggable transport, rides along to keep the TOR connection working.
A second way back in
A separate backdoor, netns, runs as a systemd service so it starts with the machine. It fetches its controller’s IPv4 address from an Ethereum smart contract (0x43eb291f56688c63c93e8a93c4591fc997cf6349) and opens a plain TCP connection to that address on port 8080, plus a reverse shell. Even if the main toolkit were removed, this door stays open.
Elastic has not named the actor behind the operation, but noted Turkish-language comments in the rootkit’s source code.
Why it matters
GPU infrastructure is expanding fast as organizations build AI workloads. Cryptojacking on a GPU host does not just steal cycles — it diverts capacity from the work the hardware was bought for and pushes costs up. Elastic’s advice is blunt: check who can submit jobs to your GPU clusters, and whether the GPU monitoring libraries have been modified. When the monitoring is the compromised part, the absence of an alert is not evidence of safety.
It fits a pattern this blog has covered before: a backdoor that survived patching on Linux hosts, and a backdoor that hid from the tools meant to find it. SANSAR combines both tricks, then adds a fake dashboard on top.
What to check
- Lock down job submission. Audit every Ray agent — and any similar job endpoint — reachable from outside your network. If a cluster accepts jobs from the internet, it accepts an attacker’s jobs. Restrict access to trusted networks, require authentication, log every submission.
- Verify your GPU monitoring stack. Compare the NVML library and nvidia-smi binaries against known-good copies — hashes from a fresh install or your package manager. A modified library is the whole trick; a hash check is the fastest way to catch it.
- Cross-check the readings. Do not trust one telemetry source. Compare nvidia-smi output with power draw at the rack or the cloud bill, host CPU load, and an independent process listing. A GPU reporting 0% while the power meter disagrees is a finding, not a glitch.
- Hunt for the persistence. Look for unfamiliar authorized_keys entries, new systemd services, kernel modules you did not install, and anything staged under /opt. A reboot that does not clear a suspicious module is a strong signal the boot image is involved.
The dashboard is only as honest as the software feeding it. SANSAR’s operators understood that — and built their whole operation around it.